Hybrid AI assistant & privacy
How Auto mode balances on-device Gemma 4 (LiteRT-LM) and Gemini BYOK with the Privacy Gatekeeper, real limits, and official model catalog.
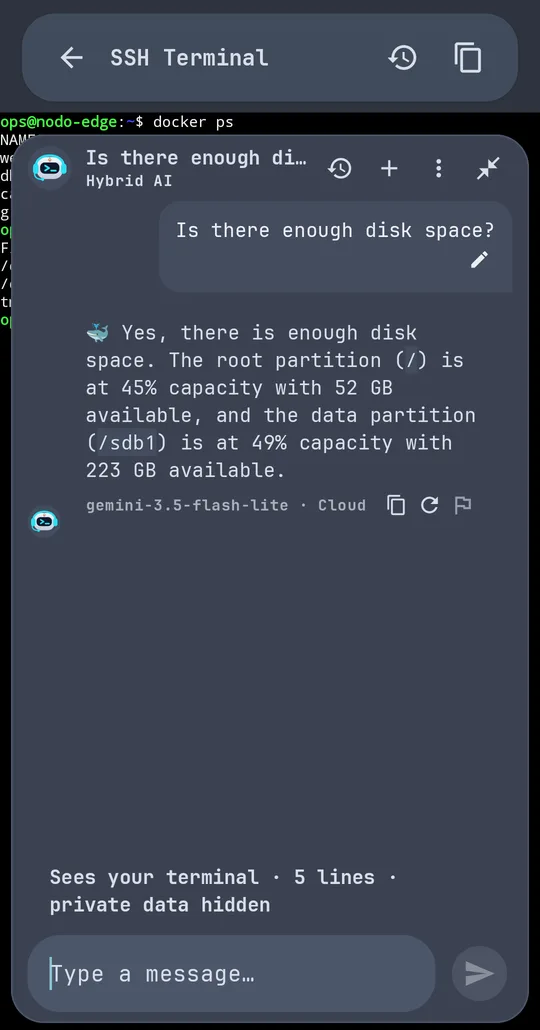
STALMAS features a technical assistant that explains container logs, analyzes Compose files, and assists inside your SSH terminal without routing prompts through any backend of ours. Every reply displays its engine tag (CLOUD: or LOCAL:), streams with a stop button, supports temporary chats (never saved), and keeps chats isolated per server or environment.
Two engines: Local (Gemma 4) & Cloud (Gemini BYOK)
- Local AI (Pro): runs quantized
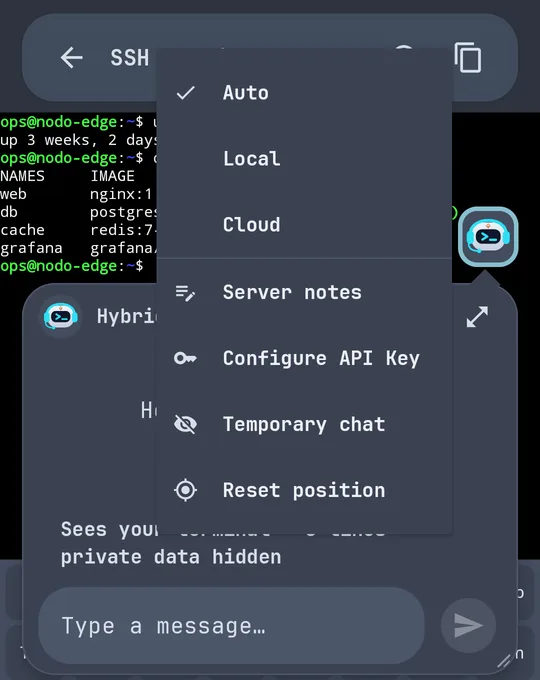
.litertlmGemma 4 models on LiteRT-LM inside an isolated:aiprocess on your Android device. Inference makes zero network requests and defaults to the Auto accelerator (automatically selects GPU or CPU per device and model, with manual override). - Cloud AI (Free & Pro): connects straight from your device to Google Gemini using your own API key (BYOK — Bring Your Own Key). Includes a dynamic model selector filtered to your key, an estimated tier checker (Free / Paid), and a 7-day local usage counter.
- Hybrid
Auto/Local/Cloudmode: on Pro you can enable “Local AI first”, enforce “Local AI only” per server, or use your Gemini key when you need a larger context window.
Gemini free tier disclosure: As stated by Google and displayed inside STALMAS AI settings, prompts sent under Gemini’s free API tier may be used by Google to improve their products. Use local Gemma 4 models or a paid Gemini billing tier when handling sensitive production context.
Official local model catalog
The .litertlm models listed in models.json are (requires Android 12+, 64-bit CPU, and free storage equal to model size + 500 MB):
| Model | License | Min recommended RAM | Approx. download |
|---|---|---|---|
Gemma 4 E2B IT (gemma-4-e2b-it) |
Apache 2.0 | 6 GB | ~2.41 GiB |
Gemma 4 E4B IT (gemma-4-e4b-it) |
Apache 2.0 | 8 GB | ~3.41 GiB |
You can also browse compatible chat models on Hugging Face or import a local .litertlm file via Android’s document picker (SAF); incompatible -gpu. / -web. variants are filtered out.
Privacy Gatekeeper (PrivateInfoDetector + PseudonymMap)
Before cloud requests leave your phone:
- It scans text for IPv4/IPv6 addresses, domains, URLs, passwords, keys, tokens, and connection strings.
- “Redact and send” (Free & cloud on Pro): the Gatekeeper does not block your workflow; it masks sensitive strings with
[REDACTED], sends the prompt, and shows a notice with how many items were masked plus “view what was redacted”. - Reversible pseudonyms (Pro): for cloud calls, IP addresses and hostnames are replaced with reversible placeholders (
[IP_1],[HOST_1]) and restored locally on screen when the reply arrives. Passwords, keys, and tokens are never restored (they remain[REDACTED]). InAutomode with a local model installed, prompts containing private data are automatically routed on-device.
Dangerous command confirmation
Whenever the assistant proposes a destructive command (such as rm -rf or docker system prune), STALMAS requires explicit mandatory confirmation before running it in the terminal, even if quick execution is enabled. The assistant never runs commands or edits files on its own.
Real context and memory limits
| Item | Free (cloud) | Pro (cloud) | Pro (local AI · LiteRT-LM) |
|---|---|---|---|
| Recent conversation memory | 6 messages (3 exchanges) | 20 messages (10 exchanges) | Up to 6 messages within 40% of the local budget |
| Terminal screen context | 4,000 characters | 16,000 characters | 1,500 characters (subject to budget) |
| Stack context (Compose) | Paste manually | 16,000 characters (head) | Up to 1,500 characters |
| Log context | Paste manually | Last 100 filtered lines (max 16,000 characters) | Last 100 filtered lines (max 1,500 characters) |
| Per-server notes | — | 1,500 characters | 1,500 characters |
| Total context window | Per chosen Gemini model | Per chosen Gemini model | 4,000 shared characters (maxNumTokens <= 4,000) |
Pro also unlocks one-tap Compose review with direct editor injection, safe storage cleanup checks, custom skills (SKILL.md), full-text chat search, and Markdown export.